Sports film review benchmark
Which coding agent and vision model reviews sports film best, on synthetic drills? Each run is scored against ground truth the tool drew into the videos, so every number is measured, not judged.
Headline: what reasoning effort changed
Frames track: stills only, no code. Every run drew svc-bench-3 from a new, unseen seed.
- Haiku 5.5 Claude Code
default 0.198 (n=1) · high 0.564 (n=1) - Opus 5.5 Claude Code
default 0.997 (n=2, 0.994–1.000) · low 0.778 (n=1) - Sonnet 5.5 Claude Code
default 0.419 (n=2, 0.413–0.426) · high 0.931 (n=4, 0.856–0.994) · max: no answer, timed out, scored 0 (n=2)
Score = above chance: 0 = no better than a blind guess that sees no video, 1 = perfect.
13 runs, 3 of 7 settings ran once, all by mariusDing, who wrote the tool. Chart and every run
Rerun it on your agent (change --model for another model; leave out --effort for the default)
uv tool install git+https://github.com/mariusDing/sports-video-coach@74b517fc410944fefeac2979810656ed77fb8f1a
sports-video-coach bench run --agent claude --model claude-sonnet-5-5 --effort high --seed --suite svc-bench-3 --track framesIt is part of sports-video-coach, a free MIT tool: your coding agent reviews your own sports video and writes you a coaching page with clips and drills. See a demo coaching page.
The findings in short: what effort changed, the blind floor, local models, cost.
- Suites svc-bench-3, svc-bench-2, svc-bench-1
- 37 runs
- Measured truth only
- Latest run 2026-10-25
Count it yourself
The juggle-touches task of svc-bench-3: the same 29.76 s video every contender got, with no answer drawn on it. Watch it, count, type your number; only then does the page show the truth and what each model answered.
The task text the contenders got:
Two players juggle identical small yellow balls with one foot, side view: the red player on the left and the orange-red player on the right. Count the touches of the left (red) player: every time his foot touches his ball. A quick double touch (the ball hops a little off the foot and is touched again at once) is two touches. A bounce of the ball on the floor is not a touch. The right player's touches do not count. The camera is hand-held.
Counted? Open for the truth and every model's answer
Truth: 47 touches
- Opus 5.5 frames track47, 47
- Codex · gpt-6-astra frames track47
- Haiku 5.5 frames track60
- Sonnet 5.5 frames track60, 75
- Fable 5.1 frames track–, 49
- Ollama · qwen3-vl:4b-instruct-q4_K_M frames track100
- Sonnet 5.5 code track46, 51
- Blind guess (no video seen)5
How the bench scores a count: 1 - |error| / truth, never below 0.
Frames track: the model saw stills of this video, one every 0.08 s, and ran no code. Code track: it could write and run its own tracker. The blind guess copies the example in the task text.
Answers as stored in benchmark/results, one per run; exact ones in green; – = the run gave no answer.
Before you trust this: 11 things a skeptic asks first
- Who ran it: all 37 runs were submitted by mariusDing, who also wrote this tool; no outside runs yet.
- Own config: 8 of 37 runs say in Settings that the submitter's own agent config (CLAUDE.md, AGENTS.md or Codex config) was loaded.
- Sample size: 19 of 27 contenders (per suite and track) ran once. Two runs with identical settings differed by up to 0.224 above chance (claude-sonnet-5-5, svc-bench-3 frames track): read smaller gaps as noise. A run killed at its time limit scores 0 and widens its contender's range further.
- Settings: not equalized. Each row ran at the effort and flags its Settings column names.
- Truth: the tool draws the videos from numbers, so the truth is exact. No human labels, no judge model.
- Public truth: the published suites and their truth ship in the open package, so a model could have seen them in training; 15 of 37 runs drew svc-bench-3 from a fresh seed (
--seed) at run time, which reduces the effect of memorising the public answers but proves nothing about training data. The agent's folder never held that truth; the result file and this page do, so a published seed is spent. - Suite design: svc-bench-2 and svc-bench-3 were each built after models scored 1.0 on the suite before, so the author knew which models already saturated it.
- Prompt:
bench runsends one fixed text per track, the same for every model; only the Claude Code frames rows are known to have run with it. See the exact prompt. - Above chance: measured from a blind guess that copies the example answers in the task text, not from random. That guess alone scores up to 0.83 on one task (shot-outcomes-hard).
- Evidence: 37 of 37 runs link a transcript (in its Evidence column): every file the agent opened, every command it ran and its final reply, with images, home folders and key-like strings taken out. Anyone can read them; CI re-scores the answers but does not read the transcripts.
- Time and cost: in every table; time recorded for 37 of 37 runs, cost for 24 of 37.
Leaderboard
Code track: the agent may write and run its own tracker. The frames-only track, where the agent reviews by eye, is further down.
svc-bench-3
Eyes: four drawn videos whose events are small, short or hidden: a ball 5 px in radius on a 640x360 frame, a ball 3 px in radius at a 16 px wide far rim, double touches 0.24 s apart, a banner and a defender in front of the moment, pass fakes, and decoys with nearly the same answer (a second juggler, a second pair passing, a far boat at a close rate).
Summary
| # | Agent | Model | Settings | Runs (n) | Mean total | Mean above chance | Range | Mean time | Mean cost |
|---|---|---|---|---|---|---|---|---|---|
| 1 | Claude Code | claude-sonnet-5-5 | runner's own agent config (--use-my-config) | 1 | 0.995 | 0.994 | - | 214 s | $0.61 |
| 2 | Claude Code | claude-sonnet-5-5 | clean-room: no user config | 1 | 0.958 | 0.951 | - | 264 s | $0.67 |
Ranked by mean above chance; “=” marks a tie. n = runs of that agent, model and settings; range = lowest to highest above-chance total over them (a dash for a single run). A run whose settings only add a note (such as being killed at the time limit) counts with its contender. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded.
Every run
| # | Agent | Model | Settings | juggle-touches | far-hoop-shots | pass-releases | stroke-rate | Total | Above chance | Time | Cost | Date | Submitter | Evidence |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | Claude Code 2.1.310 | claude-sonnet-5-5 | runner's own agent config (--use-my-config) | 0.98 | 1.00 | 1.00 | 1.00 | 0.995 | 0.994 | 214 s | $0.61 | 2026-10-24 | mariusDing | transcript |
| 2 | Claude Code 2.1.310 | claude-sonnet-5-5 | clean-room: no user config | 0.92 | 1.00 | 0.92 | 1.00 | 0.958 | 0.951 | 264 s | $0.67 | 2026-10-24 | mariusDing | transcript |
| floor | Floor: blind baseline (no video seen) | - | answers copied from the TASKS.md examples; no video or still seen | 0.11 | 0.50 | 0.17 | 0.55 | 0.331 | 0.000 | - | - | 2026-10-24 | - | - |
Scores 0 to 1 per task; total = mean. Ranked by total, then earlier date. Above chance: per task, (score - floor) / (1 - floor), clipped to 0..1, where the floor is the score of the blind baseline (it copies the example answers from the task text and sees no video); 0 = no better than that guess, 1 = perfect. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded. Raw files: benchmark/results.
Where each contender fails
Every contender run, task by task: the truth (from the suite), each run's answer as its result file stores it, the score recomputed from the two, and what was missed. The blind baseline is left out. Timestamps: an event not answered within 0.5 s still earns part of its point up to 2 s off; an unmatched answer is one with no event within 0.5 s.
juggle-touchescount
Truth: 47
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-sonnet-5-5 run 1 | 46 | 0.98 | 1 too few |
| claude-sonnet-5-5 run 2 | 51 | 0.92 | 4 too many |
far-hoop-shotsoutcomes
Truth: 6 made, 6 missed: M x M x x M M x x M x M (M = made)
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-sonnet-5-5 run 1 | 6 made, 6 missed | 1.00 | exact |
| claude-sonnet-5-5 run 2 | 6 made, 6 missed | 1.00 | exact |
pass-releasestimestamps
Truth: 12 times: 1, 3, 4.48, 5.28, 7.16, 9.48, 11.48, 12.16, 14.56, 15.84, 17.76, 19.32 s
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-sonnet-5-5 run 1 | 12 times | 1.00 | all within 0.5 s |
| claude-sonnet-5-5 run 2 | 11 times | 0.92 | 1 of 12 not within 0.5 s (at 5.28 s) |
stroke-raterate
Truth: 33.92
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-sonnet-5-5 run 1 | 34.1 | 1.00 | 0.5% high |
| claude-sonnet-5-5 run 2 | 33.9 | 1.00 | 0.1% low |
svc-bench-2
Hard: five drawn videos with a hand-held camera, look-alike decoys (a second ball, two identical feet, a rebounder), rule-defined events and noise.
Summary
| # | Agent | Model | Settings | Runs (n) | Mean total | Mean above chance | Range | Mean time | Mean cost |
|---|---|---|---|---|---|---|---|---|---|
| 1= | Claude Code | claude-sonnet-5-5 | user CLAUDE.md loaded | 1 | 1.000 | 1.000 | - | 339 s | $1.08 |
| 1= | Codex | gpt-6-astra | reasoning effort xhigh, user config loaded | 1 | 1.000 | 1.000 | - | 492 s | - |
| 3 | Claude Code | claude-opus-5-5 | user CLAUDE.md loaded | 1 | 0.960 | 0.956 | - | 262 s | $1.40 |
| 4 | OpenCode | opencode/deepseek-v4.1-flash-free | preset, run by the maintainer (--agent opencode); runner's own config; fresh OpenCode install, empty config, no account (free OpenCode Zen model); OpenCode Zen's free usage limit was reached about 1130 s in, with answers.json still unwritten | 1 | 0.000 | 0.000 | - | 1200 s | - |
Ranked by mean above chance; “=” marks a tie. n = runs of that agent, model and settings; range = lowest to highest above-chance total over them (a dash for a single run). A run whose settings only add a note (such as being killed at the time limit) counts with its contender. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded.
Every run
| # | Agent | Model | Settings | dribble-count | squat-reps | cadence-change | cone-touches-pan | shot-outcomes-hard | Total | Above chance | Time | Cost | Date | Submitter | Evidence |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | Claude Code 2.1.310 | claude-sonnet-5-5 | user CLAUDE.md loaded | 1.00 | 1.00 | 1.00 | 1.00 | 1.00 | 1.000 | 1.000 | 339 s | $1.08 | 2026-10-24 | mariusDing | transcript |
| 2 | Codex 0.159.3 | gpt-6-astra | reasoning effort xhigh, user config loaded | 1.00 | 1.00 | 1.00 | 1.00 | 1.00 | 1.000 | 1.000 | 492 s | - | 2026-10-24 | mariusDing | transcript |
| 3 | Claude Code 2.1.310 | claude-opus-5-5 | user CLAUDE.md loaded | 1.00 | 1.00 | 1.00 | 0.80 | 1.00 | 0.960 | 0.956 | 262 s | $1.40 | 2026-10-24 | mariusDing | transcript |
| 4 | OpenCode 1.19.4 | opencode/deepseek-v4.1-flash-free | preset, run by the maintainer (--agent opencode); runner's own config; fresh OpenCode install, empty config, no account (free OpenCode Zen model); OpenCode Zen's free usage limit was reached about 1130 s in, with answers.json still unwritten | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.000 | 0.000 | 1200 s | - | 2026-10-25 | mariusDing | transcript |
| floor | Floor: blind baseline (no video seen) | - | answers copied from the TASKS.md examples; no video or still seen | 0.09 | 0.62 | 0.14 | 0.09 | 0.83 | 0.356 | 0.000 | - | - | 2026-10-24 | - | - |
Scores 0 to 1 per task; total = mean. Ranked by total, then earlier date. Above chance: per task, (score - floor) / (1 - floor), clipped to 0..1, where the floor is the score of the blind baseline (it copies the example answers from the task text and sees no video); 0 = no better than that guess, 1 = perfect. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded. Raw files: benchmark/results.
Where each contender fails
Every contender run, task by task: the truth (from the suite), each run's answer as its result file stores it, the score recomputed from the two, and what was missed. The blind baseline is left out. Timestamps: an event not answered within 0.5 s still earns part of its point up to 2 s off; an unmatched answer is one with no event within 0.5 s.
dribble-countcount
Truth: 56
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 56 | 1.00 | exact |
| claude-sonnet-5-5 | 56 | 1.00 | exact |
| gpt-6-astra | 56 | 1.00 | exact |
| opencode/deepseek-v4.1-flash-free | - | 0.00 | no answer given |
squat-repscount
Truth: 8
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 8 | 1.00 | exact |
| claude-sonnet-5-5 | 8 | 1.00 | exact |
| gpt-6-astra | 8 | 1.00 | exact |
| opencode/deepseek-v4.1-flash-free | - | 0.00 | no answer given |
cadence-changerate
Truth: 182.186
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 182.2 | 1.00 | 0.0% high |
| claude-sonnet-5-5 | 182 | 1.00 | 0.1% low |
| gpt-6-astra | 182.2 | 1.00 | 0.0% high |
| opencode/deepseek-v4.1-flash-free | - | 0.00 | no answer given |
cone-touches-pantimestamps
Truth: 10 times: 3.6, 7.6, 10.6, 11, 11.4, 14.8, 19.6, 22, 23.2, 26.6 s
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 8 times | 0.80 | 2 of 10 not within 0.5 s (at 7.6 s, 19.6 s) |
| claude-sonnet-5-5 | 10 times | 1.00 | all within 0.5 s |
| gpt-6-astra | 10 times | 1.00 | all within 0.5 s |
| opencode/deepseek-v4.1-flash-free | - | 0.00 | no answer given |
shot-outcomes-hardoutcomes
Truth: 6 made, 6 missed: M x x M M x M x M x M x (M = made)
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 6 made, 6 missed | 1.00 | exact |
| claude-sonnet-5-5 | 6 made, 6 missed | 1.00 | exact |
| gpt-6-astra | 6 made, 6 missed | 1.00 | exact |
| opencode/deepseek-v4.1-flash-free | - | 0.00 | no answer given |
svc-bench-1
Four short drawn videos on a still camera. Saturated on this track: all 3 runs scored 1.0, so it ranks nobody.
Summary
| # | Agent | Model | Settings | Runs (n) | Mean total | Mean above chance | Range | Mean time | Mean cost |
|---|---|---|---|---|---|---|---|---|---|
| 1= | Claude Code | claude-opus-5-5 | claude -p, default effort, 1M context, user CLAUDE.md loaded | 1 | 1.000 | 1.000 | - | 87 s | - |
| 1= | Claude Code | claude-sonnet-5-5 | claude -p, default effort, user CLAUDE.md loaded; cost 0.33 USD | 1 | 1.000 | 1.000 | - | 55 s | - |
| 1= | Codex | - | codex exec, default settings, user config loaded (model not recorded in the run log) | 1 | 1.000 | 1.000 | - | 218 s | - |
Ranked by mean above chance; “=” marks a tie. n = runs of that agent, model and settings; range = lowest to highest above-chance total over them (a dash for a single run). A run whose settings only add a note (such as being killed at the time limit) counts with its contender. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded.
Every run
| # | Agent | Model | Settings | jump-count | stroke-rate | cone-touches | shot-outcomes | Total | Above chance | Time | Cost | Date | Submitter | Evidence |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | Claude Code 2.1.310 | claude-opus-5-5 | claude -p, default effort, 1M context, user CLAUDE.md loaded | 1.00 | 1.00 | 1.00 | 1.00 | 1.000 | 1.000 | 87 s | - | 2026-10-24 | mariusDing | transcript |
| 2 | Claude Code 2.1.310 | claude-sonnet-5-5 | claude -p, default effort, user CLAUDE.md loaded; cost 0.33 USD | 1.00 | 1.00 | 1.00 | 1.00 | 1.000 | 1.000 | 55 s | - | 2026-10-24 | mariusDing | transcript |
| 3 | Codex 0.159.3 | - | codex exec, default settings, user config loaded (model not recorded in the run log) | 1.00 | 1.00 | 1.00 | 1.00 | 1.000 | 1.000 | 218 s | - | 2026-10-24 | mariusDing | transcript |
| floor | Floor: blind baseline (no video seen) | - | answers copied from the TASKS.md examples; no video or still seen | 0.39 | 0.00 | 0.11 | 0.80 | 0.324 | 0.000 | - | - | 2026-10-24 | - | - |
Scores 0 to 1 per task; total = mean. Ranked by total, then earlier date. Above chance: per task, (score - floor) / (1 - floor), clipped to 0..1, where the floor is the score of the blind baseline (it copies the example answers from the task text and sees no video); 0 = no better than that guess, 1 = perfect. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded. Raw files: benchmark/results.
Where each contender fails
Every contender run, task by task: the truth (from the suite), each run's answer as its result file stores it, the score recomputed from the two, and what was missed. The blind baseline is left out. Timestamps: an event not answered within 0.5 s still earns part of its point up to 2 s off; an unmatched answer is one with no event within 0.5 s.
jump-countcount
Truth: 13
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 13 | 1.00 | exact |
| claude-sonnet-5-5 | 13 | 1.00 | exact |
| Codex | 13 | 1.00 | exact |
stroke-raterate
Truth: 42
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 42 | 1.00 | exact |
| claude-sonnet-5-5 | 42 | 1.00 | exact |
| Codex | 42 | 1.00 | exact |
cone-touchestimestamps
Truth: 7 times: 3.2, 5.4, 6.8, 10.4, 12.2, 14.8, 17.4 s
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 7 times | 1.00 | all within 0.5 s |
| claude-sonnet-5-5 | 7 times | 1.00 | all within 0.5 s |
| Codex | 7 times | 1.00 | all within 0.5 s |
shot-outcomesoutcomes
Truth: 5 made, 5 missed: M x M M x x M x M x (M = made)
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 5 made, 5 missed | 1.00 | exact |
| claude-sonnet-5-5 | 5 made, 5 missed | 1.00 | exact |
| Codex | 5 made, 5 missed | 1.00 | exact |
Frames-only track (eyes)
Frames-only track: the agent sees still images of each video (contact sheets with the time under every still) and has no tool that runs code, so it must review by eye. Same videos, same truth, same scoring as the code track. The scores measure what the model saw and how much it looked: a model that opens few stills guesses, and a guess can score well.
Rerun it in one command: it prepares the suite, runs Claude Code headless with no code tools (or any CLI with --agent cmd --cmd "... {prompt}"), and scores the answers.
sports-video-coach bench run --agent claude --model <model> --suite svc-bench-3 --track framesNo local install: Open in GitHub Codespaces has uv, ffmpeg and the Claude Code and Codex CLIs ready, on your own GitHub account's free hours. Log in to your agent there, then put uv run in front of the command.
Another agent: prepare the stills, let it fill bench-frames/answers.json by eye, then score it with bench score bench-frames.
sports-video-coach bench prepare --out bench-frames --suite svc-bench-3 --track framessvc-bench-3
Eyes: four drawn videos whose events are small, short or hidden: a ball 5 px in radius on a 640x360 frame, a ball 3 px in radius at a 16 px wide far rim, double touches 0.24 s apart, a banner and a defender in front of the moment, pass fakes, and decoys with nearly the same answer (a second juggler, a second pair passing, a far boat at a close rate).
Summary
| # | Agent | Model | Settings | Runs (n) | Mean total | Mean above chance | Range | Mean time | Mean cost |
|---|---|---|---|---|---|---|---|---|---|
| 1 | Claude Code | claude-opus-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 2 | 1.000 | 1.000 | 1.000–1.000 | 494 s | $3.72 |
| 2 | Codex | gpt-6-astra | frames track; codex exec -s read-only, shell/exec/code-mode features disabled, sheets attached with -i; reasoning effort xhigh (user config) | 1 | 0.862 | 0.727 | - | 766 s | - |
| 3 | Claude Code | claude-fable-5-1 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 2 | 0.494 | 0.494 | 0.000–0.988 | 1673 s | $19.23 (1 of 2) |
| 4 | Claude Code | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 2 | 0.526 | 0.385 | 0.273–0.497 | 40 s | $0.14 |
| 5 | Claude Code | claude-haiku-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 1 | 0.585 | 0.333 | - | 136 s | $0.04 |
| 6 | Ollama | qwen3-vl:4b-instruct-q4_K_M | frames track; OpenAI-compatible chat completions on Ollama 0.40.10, weights Q4_K_M, 4.0B; one request per task (4 requests, 11-27 contact sheets each as base64 JPEG, sheets as drawn (1280 px on the longer side)), the task's section of TASKS.md and the rules in the prompt, no full-size stills, no tools; temperature 0, max_tokens 4096; server: OLLAMA_CONTEXT_LENGTH=32768, flash attention, KV cache q8_0; RTX 3070 8 GB | 1 | 0.125 | 0.000 | - | 260 s | - |
Ranked by mean above chance; “=” marks a tie. n = runs of that agent, model and settings; range = lowest to highest above-chance total over them (a dash for a single run). A run whose settings only add a note (such as being killed at the time limit) counts with its contender. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded.
Every run
| # | Agent | Model | Settings | juggle-touches | far-hoop-shots | pass-releases | stroke-rate | Total | Above chance | Time | Cost | Date | Submitter | Evidence |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | Claude Code 2.1.310 | claude-opus-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 1.00 | 1.00 | 1.00 | 1.00 | 1.000 | 1.000 | 489 s | $3.91 | 2026-10-24 | mariusDing | transcript |
| 2 | Claude Code 2.1.310 | claude-opus-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 1.00 | 1.00 | 1.00 | 1.00 | 1.000 | 1.000 | 500 s | $3.52 | 2026-10-24 | mariusDing | transcript |
| 3 | Claude Code 2.1.310 | claude-fable-5-1 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 0.96 | 1.00 | 1.00 | 1.00 | 0.989 | 0.988 | 1645 s | $19.23 | 2026-10-24 | mariusDing | transcript |
| 4 | Codex 0.159.3 | gpt-6-astra | frames track; codex exec -s read-only, shell/exec/code-mode features disabled, sheets attached with -i; reasoning effort xhigh (user config) | 1.00 | 1.00 | 0.92 | 0.53 | 0.862 | 0.727 | 766 s | - | 2026-10-24 | mariusDing | transcript |
| 5 | Claude Code 2.1.310 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 0.72 | 0.75 | 0.83 | 0.14 | 0.612 | 0.497 | 65 s | $0.23 | 2026-10-24 | mariusDing | transcript |
| 6 | Claude Code 2.1.310 | claude-haiku-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 0.72 | 0.58 | 0.56 | 0.47 | 0.585 | 0.333 | 136 s | $0.04 | 2026-10-24 | mariusDing | transcript |
| 7 | Claude Code 2.1.310 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 0.40 | 0.42 | 0.80 | 0.14 | 0.441 | 0.273 | 16 s | $0.06 | 2026-10-24 | mariusDing | transcript |
| 8 | Ollama 0.40.10 | qwen3-vl:4b-instruct-q4_K_M | frames track; OpenAI-compatible chat completions on Ollama 0.40.10, weights Q4_K_M, 4.0B; one request per task (4 requests, 11-27 contact sheets each as base64 JPEG, sheets as drawn (1280 px on the longer side)), the task's section of TASKS.md and the rules in the prompt, no full-size stills, no tools; temperature 0, max_tokens 4096; server: OLLAMA_CONTEXT_LENGTH=32768, flash attention, KV cache q8_0; RTX 3070 8 GB | 0.00 | 0.50 | 0.00 | 0.00 | 0.125 | 0.000 | 260 s | - | 2026-10-25 | mariusDing | transcript |
| 9 | Claude Code 2.1.310 | claude-fable-5-1 | frames track; claude -p --restricted --safe-mode --tools Read; default effort; killed at the 1700 s time limit before writing answers (read 548 stills) | 0.00 | 0.00 | 0.00 | 0.00 | 0.000 | 0.000 | 1700 s | - | 2026-10-24 | mariusDing | transcript |
| floor | Floor: blind baseline (no video seen) | - | answers copied from the TASKS.md examples; no video or still seen | 0.11 | 0.50 | 0.17 | 0.55 | 0.331 | 0.000 | - | - | 2026-10-24 | - | - |
Scores 0 to 1 per task; total = mean. Ranked by total, then earlier date. Above chance: per task, (score - floor) / (1 - floor), clipped to 0..1, where the floor is the score of the blind baseline (it copies the example answers from the task text and sees no video); 0 = no better than that guess, 1 = perfect. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded. Raw files: benchmark/results.
Where each contender fails
Every contender run, task by task: the truth (from the suite), each run's answer as its result file stores it, the score recomputed from the two, and what was missed. The blind baseline is left out. Timestamps: an event not answered within 0.5 s still earns part of its point up to 2 s off; an unmatched answer is one with no event within 0.5 s.
juggle-touchescount
Truth: 47
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-fable-5-1 run 1 | - | 0.00 | no answer given |
| claude-fable-5-1 run 2 | 49 | 0.96 | 2 too many |
| claude-haiku-5-5 | 60 | 0.72 | 13 too many |
| claude-opus-5-5 run 1 | 47 | 1.00 | exact |
| claude-opus-5-5 run 2 | 47 | 1.00 | exact |
| claude-sonnet-5-5 run 1 | 60 | 0.72 | 13 too many |
| claude-sonnet-5-5 run 2 | 75 | 0.40 | 28 too many |
| gpt-6-astra | 47 | 1.00 | exact |
| qwen3-vl:4b-instruct-q4_K_M | 100 | 0.00 | 53 too many |
far-hoop-shotsoutcomes
Truth: 6 made, 6 missed: M x M x x M M x x M x M (M = made)
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-fable-5-1 run 1 | - | 0.00 | no answer given |
| claude-fable-5-1 run 2 | 6 made, 6 missed | 1.00 | exact |
| claude-haiku-5-5 | 5 made, 7 missed | 0.58 | 5 of 12 wrong (#3 said missed, #4 said made, #6 said missed, #7 said missed +1 more) |
| claude-opus-5-5 run 1 | 6 made, 6 missed | 1.00 | exact |
| claude-opus-5-5 run 2 | 6 made, 6 missed | 1.00 | exact |
| claude-sonnet-5-5 run 1 | 7 made, 5 missed | 0.75 | 3 of 12 wrong (#5 said made, #7 said missed, #8 said made) |
| claude-sonnet-5-5 run 2 | 7 made, 5 missed | 0.42 | 7 of 12 wrong (#4 said made, #7 said missed, #8 said made, #9 said made +3 more) |
| gpt-6-astra | 6 made, 6 missed | 1.00 | exact |
| qwen3-vl:4b-instruct-q4_K_M | 6 made, 6 missed | 0.50 | 6 of 12 wrong (#5 said made, #6 said missed, #9 said made, #10 said missed +2 more) |
pass-releasestimestamps
Truth: 12 times: 1, 3, 4.48, 5.28, 7.16, 9.48, 11.48, 12.16, 14.56, 15.84, 17.76, 19.32 s
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-fable-5-1 run 1 | - | 0.00 | no answer given |
| claude-fable-5-1 run 2 | 12 times | 1.00 | all within 0.5 s |
| claude-haiku-5-5 | 7 times | 0.56 | 6 of 12 not within 0.5 s (at 3 s, 9.48 s, 11.48 s, 12.16 s +2 more); 1 unmatched (at 16.9 s) |
| claude-opus-5-5 run 1 | 12 times | 1.00 | all within 0.5 s |
| claude-opus-5-5 run 2 | 12 times | 1.00 | all within 0.5 s |
| claude-sonnet-5-5 run 1 | 10 times | 0.83 | 2 of 12 not within 0.5 s (at 12.16 s, 15.84 s) |
| claude-sonnet-5-5 run 2 | 10 times | 0.80 | 4 of 12 not within 0.5 s (at 4.48 s, 12.16 s, 15.84 s, 17.76 s); 2 unmatched (at 13 s, 17 s) |
| gpt-6-astra | 13 times | 0.92 | 1 unmatched (at 7.76 s) |
| qwen3-vl:4b-instruct-q4_K_M | - | 0.00 | no answer given |
stroke-raterate
Truth: 33.92
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-fable-5-1 run 1 | - | 0.00 | no answer given |
| claude-fable-5-1 run 2 | 33.9 | 1.00 | 0.1% low |
| claude-haiku-5-5 | 30 | 0.47 | 11.6% low |
| claude-opus-5-5 run 1 | 33.9 | 1.00 | 0.1% low |
| claude-opus-5-5 run 2 | 33.9 | 1.00 | 0.1% low |
| claude-sonnet-5-5 run 1 | 28 | 0.14 | 17.5% low |
| claude-sonnet-5-5 run 2 | 28 | 0.14 | 17.5% low |
| gpt-6-astra | 37.5 | 0.53 | 10.6% high |
| qwen3-vl:4b-instruct-q4_K_M | - | 0.00 | no answer given |
svc-bench-2
Hard: five drawn videos with a hand-held camera, look-alike decoys (a second ball, two identical feet, a rebounder), rule-defined events and noise.
Summary
| # | Agent | Model | Settings | Runs (n) | Mean total | Mean above chance | Range | Mean time | Mean cost |
|---|---|---|---|---|---|---|---|---|---|
| 1= | Claude Code | claude-opus-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 1 | 1.000 | 1.000 | - | 522 s | $3.04 |
| 1= | Codex | gpt-6-astra | frames track; codex exec -s read-only, shell/exec/code-mode features disabled, sheets attached with -i; reasoning effort xhigh (user config); the user's global Codex AGENTS.md was loaded (it replied in Chinese) | 1 | 1.000 | 1.000 | - | 585 s | - |
| 3 | Claude Code | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 2 | 0.701 | 0.512 | 0.460–0.564 | 45 s | $0.15 |
Ranked by mean above chance; “=” marks a tie. n = runs of that agent, model and settings; range = lowest to highest above-chance total over them (a dash for a single run). A run whose settings only add a note (such as being killed at the time limit) counts with its contender. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded.
Every run
| # | Agent | Model | Settings | dribble-count | squat-reps | cadence-change | cone-touches-pan | shot-outcomes-hard | Total | Above chance | Time | Cost | Date | Submitter | Evidence |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | Claude Code 2.1.310 | claude-opus-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 1.00 | 1.00 | 1.00 | 1.00 | 1.00 | 1.000 | 1.000 | 522 s | $3.04 | 2026-10-24 | mariusDing | transcript |
| 2 | Codex 0.159.3 | gpt-6-astra | frames track; codex exec -s read-only, shell/exec/code-mode features disabled, sheets attached with -i; reasoning effort xhigh (user config); the user's global Codex AGENTS.md was loaded (it replied in Chinese) | 1.00 | 1.00 | 1.00 | 1.00 | 1.00 | 1.000 | 1.000 | 585 s | - | 2026-10-24 | mariusDing | transcript |
| 3 | Claude Code 2.1.310 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 0.80 | 1.00 | 0.74 | 0.40 | 0.83 | 0.755 | 0.564 | 77 s | $0.24 | 2026-10-24 | mariusDing | transcript |
| 4 | Claude Code 2.1.310 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 0.80 | 0.88 | 0.74 | 0.23 | 0.58 | 0.646 | 0.460 | 12 s | $0.05 | 2026-10-24 | mariusDing | transcript |
| floor | Floor: blind baseline (no video seen) | - | answers copied from the TASKS.md examples; no video or still seen | 0.09 | 0.62 | 0.14 | 0.09 | 0.83 | 0.356 | 0.000 | - | - | 2026-10-24 | - | - |
Scores 0 to 1 per task; total = mean. Ranked by total, then earlier date. Above chance: per task, (score - floor) / (1 - floor), clipped to 0..1, where the floor is the score of the blind baseline (it copies the example answers from the task text and sees no video); 0 = no better than that guess, 1 = perfect. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded. Raw files: benchmark/results.
Where each contender fails
Every contender run, task by task: the truth (from the suite), each run's answer as its result file stores it, the score recomputed from the two, and what was missed. The blind baseline is left out. Timestamps: an event not answered within 0.5 s still earns part of its point up to 2 s off; an unmatched answer is one with no event within 0.5 s.
dribble-countcount
Truth: 56
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 56 | 1.00 | exact |
| claude-sonnet-5-5 run 1 | 45 | 0.80 | 11 too few |
| claude-sonnet-5-5 run 2 | 45 | 0.80 | 11 too few |
| gpt-6-astra | 56 | 1.00 | exact |
squat-repscount
Truth: 8
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 8 | 1.00 | exact |
| claude-sonnet-5-5 run 1 | 8 | 1.00 | exact |
| claude-sonnet-5-5 run 2 | 7 | 0.88 | 1 too few |
| gpt-6-astra | 8 | 1.00 | exact |
cadence-changerate
Truth: 182.186
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 182.2 | 1.00 | 0.0% high |
| claude-sonnet-5-5 run 1 | 170 | 0.74 | 6.7% low |
| claude-sonnet-5-5 run 2 | 170 | 0.74 | 6.7% low |
| gpt-6-astra | 182 | 1.00 | 0.1% low |
cone-touches-pantimestamps
Truth: 10 times: 3.6, 7.6, 10.6, 11, 11.4, 14.8, 19.6, 22, 23.2, 26.6 s
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 10 times | 1.00 | all within 0.5 s |
| claude-sonnet-5-5 run 1 | 4 times | 0.40 | 6 of 10 not within 0.5 s (at 3.6 s, 10.6 s, 11 s, 11.4 s +2 more) |
| claude-sonnet-5-5 run 2 | 4 times | 0.23 | 10 of 10 not within 0.5 s (at 3.6 s, 7.6 s, 10.6 s, 11 s +6 more); 4 unmatched (at 6 s, 12 s, 18 s, 24 s) |
| gpt-6-astra | 10 times | 1.00 | all within 0.5 s |
shot-outcomes-hardoutcomes
Truth: 6 made, 6 missed: M x x M M x M x M x M x (M = made)
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-opus-5-5 | 6 made, 6 missed | 1.00 | exact |
| claude-sonnet-5-5 run 1 | 6 made, 6 missed | 0.83 | 2 of 12 wrong (#3 said made, #4 said missed) |
| claude-sonnet-5-5 run 2 | 7 made, 5 missed | 0.58 | 5 of 12 wrong (#3 said made, #5 said missed, #6 said made, #7 said missed +1 more) |
| gpt-6-astra | 6 made, 6 missed | 1.00 | exact |
svc-bench-3-fresh
Fresh seeds: svc-bench-3 drawn anew for each run from the seed in its result file (`--seed`), with the same scenes and kinds of traps but new counts, outcomes, times and rates. The agent's folder never held the truth; the tool rebuilds it from the seed to score and check each row, and shows it below, so a published seed is spent. Each run's floor is the blind baseline on its own seed.
What effort changed
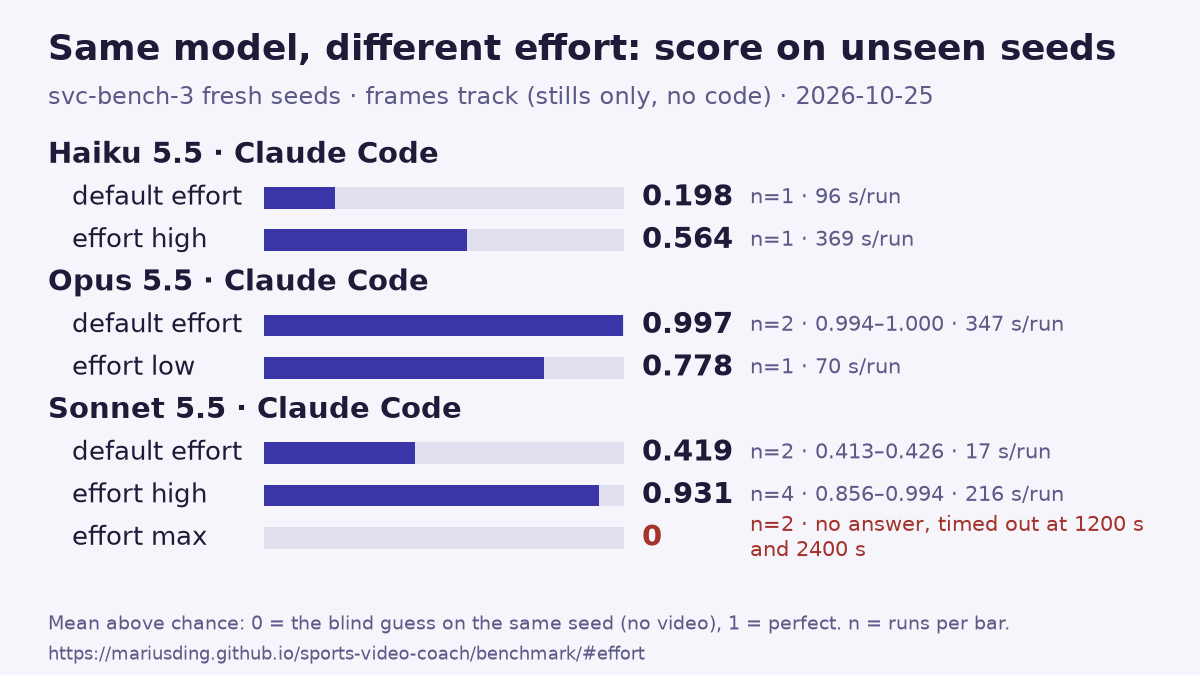
Same model, same kind of task (svc-bench-3 drawn from a new seed for every run, reviewed by eye from stills); only the effort setting changed. Mean score above chance:
- Haiku 5.5 · Claude Code
- default effort: 0.198 (1 run, 96 s)
- effort high: 0.564 (1 run, 369 s)
- Opus 5.5 · Claude Code
- default effort: 0.997 mean, range 0.994–1.000 (2 runs, 347 s per run)
- effort low: 0.778 (1 run, 70 s)
- Sonnet 5.5 · Claude Code
- default effort: 0.419 mean, range 0.413–0.426 (2 runs, 17 s per run)
- effort high: 0.931 mean, range 0.856–0.994 (4 runs, 216 s per run)
- effort max: no answer, killed at the time limit (1200 s and 2400 s), scored 0 (2 runs)
One run per setting unless n says otherwise, each on its own seed: a measured difference, not a variance estimate. Default = no effort flag (the CLI's own default). Every run is a row in the board below.
Summary
| # | Agent | Model | Settings | Runs (n) | Mean total | Mean above chance | Range | Mean time | Mean cost |
|---|---|---|---|---|---|---|---|---|---|
| 1 | Codex | gpt-6-astra | Codex: runner's own config; not isolated, so credentials stay where they are; frames track; codex exec -s read-only, shell/exec/code-mode and other tool features disabled, web search off, sheets attached with -i; beyond that tool restriction is by prompt only (the transcript shows every command it ran); reasoning effort xhigh | 1 | 1.000 | 1.000 | - | 514 s | - |
| 2 | Claude Code | claude-opus-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 2 | 0.997 | 0.997 | 0.994–1.000 | 347 s | $2.55 |
| 3 | Claude Code | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort high | 4 | 0.940 | 0.931 | 0.856–0.994 | 216 s | $0.84 |
| 4 | Claude Code | claude-opus-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort low | 1 | 0.879 | 0.778 | - | 70 s | $0.45 |
| 5 | Claude Code | claude-haiku-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort high | 1 | 0.698 | 0.564 | - | 369 s | $0.32 |
| 6 | Claude Code | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 2 | 0.543 | 0.419 | 0.413–0.426 | 17 s | $0.06 |
| 7 | Claude Code | claude-haiku-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 1 | 0.440 | 0.198 | - | 96 s | $0.06 |
| 8 | Ollama | qwen3-vl:4b-instruct-q4_K_M | frames track; OpenAI-compatible chat completions on Ollama 0.40.10, weights Q4_K_M, 4.0B; one request per task (4 requests, 11-30 contact sheets each as base64 JPEG, sheets as drawn (1280 px on the longer side)), the task's section of TASKS.md and the rules in the prompt, no full-size stills, no tools; temperature 0, max_tokens 4096; server: OLLAMA_CONTEXT_LENGTH=40960, flash attention, KV cache q8_0; RTX 3070 8 GB | 1 | 0.077 | 0.000 | - | 621 s | - |
| 9 | Claude Code | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort max | 2 | 0.000 | 0.000 | 0.000–0.000 | 1801 s | - |
Ranked by mean above chance; “=” marks a tie. n = runs of that agent, model and settings; range = lowest to highest above-chance total over them (a dash for a single run). A run whose settings only add a note (such as being killed at the time limit) counts with its contender. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded.
Every run
| # | Agent | Model | Settings | juggle-touches | far-hoop-shots | pass-releases | stroke-rate | Total | Above chance | Time | Cost | Date | Submitter | Evidence |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | Claude Code 2.1.310 seed 613104018 | claude-opus-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 1.00 | 1.00 | 1.00 | 1.00 | 1.000 | 1.000 | 378 s | $2.77 | 2026-10-25 | mariusDing | transcript |
| 2 | Codex 0.159.3 seed 911623366 | gpt-6-astra | Codex: runner's own config; not isolated, so credentials stay where they are; frames track; codex exec -s read-only, shell/exec/code-mode and other tool features disabled, web search off, sheets attached with -i; beyond that tool restriction is by prompt only (the transcript shows every command it ran); reasoning effort xhigh | 1.00 | 1.00 | 1.00 | 1.00 | 1.000 | 1.000 | 514 s | - | 2026-10-25 | mariusDing | transcript |
| 3 | Claude Code 2.1.310 seed 208632171 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort high | 0.98 | 1.00 | 1.00 | 1.00 | 0.995 | 0.994 | 256 s | $0.94 | 2026-10-25 | mariusDing | transcript |
| 4 | Claude Code 2.1.310 seed 205159368 | claude-opus-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 0.98 | 1.00 | 1.00 | 1.00 | 0.994 | 0.994 | 317 s | $2.32 | 2026-10-25 | mariusDing | transcript |
| 5 | Claude Code 2.1.310 seed 395804731 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort high | 0.98 | 1.00 | 0.92 | 1.00 | 0.974 | 0.969 | 165 s | $0.70 | 2026-10-25 | mariusDing | transcript |
| 6 | Claude Code 2.1.310 seed 288038083 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort high | 0.67 | 1.00 | 1.00 | 1.00 | 0.917 | 0.906 | 257 s | $0.99 | 2026-10-25 | mariusDing | transcript |
| 7 | Claude Code 2.1.310 seed 959964891 | claude-opus-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort low | 0.98 | 0.54 | 1.00 | 1.00 | 0.879 | 0.778 | 70 s | $0.45 | 2026-10-25 | mariusDing | transcript |
| 8 | Claude Code 2.1.310 seed 633675701 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort high | 0.50 | 1.00 | 1.00 | 1.00 | 0.875 | 0.856 | 184 s | $0.73 | 2026-10-25 | mariusDing | transcript |
| 9 | Claude Code 2.1.310 seed 778572209 | claude-haiku-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort high | 0.86 | 0.39 | 1.00 | 0.54 | 0.698 | 0.564 | 369 s | $0.32 | 2026-10-25 | mariusDing | transcript |
| 10 | Claude Code 2.1.310 seed 406013493 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 0.93 | 0.58 | 0.82 | 0.00 | 0.583 | 0.426 | 16 s | $0.06 | 2026-10-25 | mariusDing | transcript |
| 11 | Claude Code 2.1.310 seed 956466926 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 0.91 | 0.31 | 0.80 | 0.00 | 0.504 | 0.413 | 19 s | $0.07 | 2026-10-25 | mariusDing | transcript |
| 12 | Claude Code 2.1.310 seed 166697672 | claude-haiku-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; default effort | 0.50 | 0.46 | 0.25 | 0.56 | 0.440 | 0.198 | 96 s | $0.06 | 2026-10-25 | mariusDing | transcript |
| 13 | Ollama 0.40.10 seed 792092586 | qwen3-vl:4b-instruct-q4_K_M | frames track; OpenAI-compatible chat completions on Ollama 0.40.10, weights Q4_K_M, 4.0B; one request per task (4 requests, 11-30 contact sheets each as base64 JPEG, sheets as drawn (1280 px on the longer side)), the task's section of TASKS.md and the rules in the prompt, no full-size stills, no tools; temperature 0, max_tokens 4096; server: OLLAMA_CONTEXT_LENGTH=40960, flash attention, KV cache q8_0; RTX 3070 8 GB | 0.00 | 0.31 | 0.00 | 0.00 | 0.077 | 0.000 | 621 s | - | 2026-10-25 | mariusDing | transcript |
| 14 | Claude Code 2.1.310 seed 280902796 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort max | 0.00 | 0.00 | 0.00 | 0.00 | 0.000 | 0.000 | 1200 s | - | 2026-10-25 | mariusDing | transcript |
| 15 | Claude Code 2.1.310 seed 604284533 | claude-sonnet-5-5 | frames track; claude -p --restricted --safe-mode --tools Read; effort max | 0.00 | 0.00 | 0.00 | 0.00 | 0.000 | 0.000 | 2401 s | - | 2026-10-25 | mariusDing | transcript |
Scores 0 to 1 per task; total = mean. Ranked by total, then earlier date. Above chance: per task, (score - floor) / (1 - floor), clipped to 0..1, where the floor is the score of the blind baseline (it copies the example answers from the task text and sees no video); 0 = no better than that guess, 1 = perfect. Time = wall seconds the run took; cost = USD the agent itself reported (Claude Code does, Codex does not); '-' = not recorded. Raw files: benchmark/results.
Where each contender fails
Every contender run, task by task: the truth (from the suite), each run's answer as its result file stores it, the score recomputed from the two, and what was missed. The blind baseline is left out. Timestamps: an event not answered within 0.5 s still earns part of its point up to 2 s off; an unmatched answer is one with no event within 0.5 s.
juggle-touchescount
Truth: drawn from each run's own seed; shown in its row
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-haiku-5-5 run 1 (seed 166697672) | 60 | 0.50 | truth 40; 20 too many |
| claude-haiku-5-5 run 2 (seed 778572209) | 50 | 0.86 | truth 44; 6 too many |
| claude-opus-5-5 run 1 (seed 205159368) | 44 | 0.98 | truth 45; 1 too few |
| claude-opus-5-5 run 2 (seed 613104018) | 41 | 1.00 | truth 41; exact |
| claude-opus-5-5 run 3 (seed 959964891) | 42 | 0.98 | truth 41; 1 too many |
| claude-sonnet-5-5 run 1 (seed 208632171) | 50 | 0.98 | truth 49; 1 too many |
| claude-sonnet-5-5 run 2 (seed 280902796) | - | 0.00 | truth 49; no answer given |
| claude-sonnet-5-5 run 3 (seed 288038083) | 56 | 0.67 | truth 42; 14 too many |
| claude-sonnet-5-5 run 4 (seed 395804731) | 45 | 0.98 | truth 44; 1 too many |
| claude-sonnet-5-5 run 5 (seed 406013493) | 48 | 0.93 | truth 45; 3 too many |
| claude-sonnet-5-5 run 6 (seed 604284533) | - | 0.00 | truth 48; no answer given |
| claude-sonnet-5-5 run 7 (seed 633675701) | 60 | 0.50 | truth 40; 20 too many |
| claude-sonnet-5-5 run 8 (seed 956466926) | 38 | 0.91 | truth 42; 4 too few |
| gpt-6-astra (seed 911623366) | 47 | 1.00 | truth 47; exact |
| qwen3-vl:4b-instruct-q4_K_M (seed 792092586) | 100 | 0.00 | truth 50; 50 too many |
far-hoop-shotsoutcomes
Truth: drawn from each run's own seed; shown in its row
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-haiku-5-5 run 1 (seed 166697672) | 4 made, 7 missed | 0.46 | truth 6 made, 5 missed: x M x M M M M M x x x (M = made); 6 of 11 wrong (#2 said missed, #3 said made, #4 said missed, #6 said missed +2 more) |
| claude-haiku-5-5 run 2 (seed 778572209) | 4 made, 9 missed | 0.39 | truth 4 made, 9 missed: x x M x x M M x x x x M x (M = made); 8 of 13 wrong (#3 said missed, #4 said made, #6 said missed, #7 said missed +4 more) |
| claude-opus-5-5 run 1 (seed 205159368) | 4 made, 7 missed | 1.00 | truth 4 made, 7 missed: M M x M x x x x M x x (M = made); exact |
| claude-opus-5-5 run 2 (seed 613104018) | 5 made, 6 missed | 1.00 | truth 5 made, 6 missed: x x M M x x M M x M x (M = made); exact |
| claude-opus-5-5 run 3 (seed 959964891) | 8 made, 5 missed | 0.54 | truth 6 made, 7 missed: M M x M x x x x M x x M M (M = made); 6 of 13 wrong (#2 said missed, #3 said made, #6 said made, #8 said made +2 more) |
| claude-sonnet-5-5 run 1 (seed 208632171) | 5 made, 8 missed | 1.00 | truth 5 made, 8 missed: x M x x x x M x M x x M M (M = made); exact |
| claude-sonnet-5-5 run 2 (seed 280902796) | - | 0.00 | truth 8 made, 5 missed: M M x x M x x M M M M x M (M = made); no answer given |
| claude-sonnet-5-5 run 3 (seed 288038083) | 7 made, 6 missed | 1.00 | truth 7 made, 6 missed: x M M M M x x x M M M x x (M = made); exact |
| claude-sonnet-5-5 run 4 (seed 395804731) | 7 made, 5 missed | 1.00 | truth 7 made, 5 missed: M x x M M M M M x x x M (M = made); exact |
| claude-sonnet-5-5 run 5 (seed 406013493) | 6 made, 6 missed | 0.58 | truth 5 made, 7 missed: M M M x x x x x M M x x (M = made); 5 of 12 wrong (#2 said missed, #5 said made, #7 said made, #10 said missed +1 more) |
| claude-sonnet-5-5 run 6 (seed 604284533) | - | 0.00 | truth 5 made, 7 missed: M M M x x M x x x x x M (M = made); no answer given |
| claude-sonnet-5-5 run 7 (seed 633675701) | 6 made, 7 missed | 1.00 | truth 6 made, 7 missed: x M M x x x M M x M x x M (M = made); exact |
| claude-sonnet-5-5 run 8 (seed 956466926) | 7 made, 6 missed | 0.31 | truth 4 made, 9 missed: x M x x x x x M M x M x x (M = made); 9 of 13 wrong (#1 said made, #2 said missed, #3 said made, #5 said made +5 more) |
| gpt-6-astra (seed 911623366) | 6 made, 7 missed | 1.00 | truth 6 made, 7 missed: x M x M M x M M x x x M x (M = made); exact |
| qwen3-vl:4b-instruct-q4_K_M (seed 792092586) | 7 made, 6 missed | 0.31 | truth 8 made, 5 missed: x M x M M M x M M x x M M (M = made); 9 of 13 wrong (#1 said made, #2 said missed, #3 said made, #4 said missed +5 more) |
pass-releasestimestamps
Truth: drawn from each run's own seed; shown in its row
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-haiku-5-5 run 1 (seed 166697672) | 3 times | 0.25 | truth 12 times: 0.72, 2.24, 3.32, 4, 5.6, 6.8, 7.96, 10.56, 12.56, 14.44, 16.88, 18.8 s; 9 of 12 not within 0.5 s (at 2.24 s, 4 s, 5.6 s, 6.8 s +5 more) |
| claude-haiku-5-5 run 2 (seed 778572209) | 12 times | 1.00 | truth 12 times: 1.88, 2.68, 3.76, 5.56, 7.28, 9.76, 10.96, 12.8, 14.12, 16.04, 16.72, 18.8 s; all within 0.5 s |
| claude-opus-5-5 run 1 (seed 205159368) | 11 times | 1.00 | truth 11 times: 0.4, 1.08, 2.84, 5.4, 7.72, 10.4, 11.52, 12.2, 13.6, 15.2, 17.32 s; all within 0.5 s |
| claude-opus-5-5 run 2 (seed 613104018) | 11 times | 1.00 | truth 11 times: 1.4, 3.16, 5.64, 6.84, 8.88, 9.56, 11.4, 13.24, 15.56, 17.56, 19.24 s; all within 0.5 s |
| claude-opus-5-5 run 3 (seed 959964891) | 12 times | 1.00 | truth 12 times: 1.2, 3.88, 5.84, 7.6, 8.28, 10.64, 12.32, 14.28, 15.08, 16.88, 18.08, 19.6 s; all within 0.5 s |
| claude-sonnet-5-5 run 1 (seed 208632171) | 11 times | 1.00 | truth 11 times: 0.76, 1.96, 3.8, 5.88, 8.4, 9.88, 11.48, 13.92, 15.6, 16.28, 18.72 s; all within 0.5 s |
| claude-sonnet-5-5 run 2 (seed 280902796) | - | 0.00 | truth 11 times: 1, 3.08, 5.92, 7.12, 9.24, 11.4, 12.8, 13.88, 14.96, 16.76, 19.16 s; no answer given |
| claude-sonnet-5-5 run 3 (seed 288038083) | 12 times | 1.00 | truth 12 times: 0.52, 2.4, 4.2, 6.12, 7.28, 9.04, 10.28, 12, 12.68, 14.52, 16.4, 18.36 s; all within 0.5 s |
| claude-sonnet-5-5 run 4 (seed 395804731) | 11 times | 0.92 | truth 12 times: 0.56, 1.36, 2.84, 3.52, 5.76, 7.72, 9.48, 10.88, 11.56, 13.68, 15.08, 16.68 s; 1 of 12 not within 0.5 s (at 1.36 s) |
| claude-sonnet-5-5 run 5 (seed 406013493) | 10 times | 0.82 | truth 11 times: 0.4, 1.6, 3.48, 5.72, 7.4, 9.92, 12.4, 14.44, 16.04, 17.24, 19.04 s; 6 of 11 not within 0.5 s (at 1.6 s, 3.48 s, 5.72 s, 7.4 s +2 more); 5 unmatched (at 2.4 s, 4.4 s, 6.4 s, 8.4 s +1 more) |
| claude-sonnet-5-5 run 6 (seed 604284533) | - | 0.00 | truth 12 times: 0.6, 2.24, 2.92, 4.2, 5.4, 7.72, 8.4, 10.24, 12.16, 14.8, 16.68, 19 s; no answer given |
| claude-sonnet-5-5 run 7 (seed 633675701) | 12 times | 1.00 | truth 12 times: 0.76, 1.44, 3.2, 4.8, 5.48, 7.36, 8.96, 10.92, 12.76, 15.08, 17.04, 18.92 s; all within 0.5 s |
| claude-sonnet-5-5 run 8 (seed 956466926) | 11 times | 0.80 | truth 11 times: 0.8, 2, 4.2, 4.88, 7.04, 8.76, 10.44, 12.4, 14.12, 16.08, 19.04 s; 8 of 11 not within 0.5 s (at 2 s, 4.88 s, 7.04 s, 8.76 s +4 more); 8 unmatched (at 2.6 s, 6.2 s, 8 s, 9.8 s +4 more) |
| gpt-6-astra (seed 911623366) | 11 times | 1.00 | truth 11 times: 1.6, 3.28, 5.56, 7.88, 9.16, 10.6, 12.92, 14.12, 15.64, 16.92, 18.36 s; all within 0.5 s |
| qwen3-vl:4b-instruct-q4_K_M (seed 792092586) | - | 0.00 | truth 11 times: 1.52, 3.6, 4.28, 6, 6.68, 7.8, 9.28, 11.28, 12.56, 13.76, 15.92 s; no answer given |
stroke-raterate
Truth: drawn from each run's own seed; shown in its row
| Run | Answer | Score | What was missed |
|---|---|---|---|
| claude-haiku-5-5 run 1 (seed 166697672) | 30 | 0.56 | truth 33.333; 10.0% low |
| claude-haiku-5-5 run 2 (seed 778572209) | 40 | 0.54 | truth 36.29; 10.2% high |
| claude-opus-5-5 run 1 (seed 205159368) | 33.1 | 1.00 | truth 33.149; 0.1% low |
| claude-opus-5-5 run 2 (seed 613104018) | 35.1 | 1.00 | truth 35.156; 0.2% low |
| claude-opus-5-5 run 3 (seed 959964891) | 33 | 1.00 | truth 32.698; 0.9% high |
| claude-sonnet-5-5 run 1 (seed 208632171) | 33 | 1.00 | truth 32.967; 0.1% high |
| claude-sonnet-5-5 run 2 (seed 280902796) | - | 0.00 | truth 34.884; no answer given |
| claude-sonnet-5-5 run 3 (seed 288038083) | 37.5 | 1.00 | truth 37.5; exact |
| claude-sonnet-5-5 run 4 (seed 395804731) | 37 | 1.00 | truth 36.29; 2.0% high |
| claude-sonnet-5-5 run 5 (seed 406013493) | 28 | 0.00 | truth 36.388; 23.1% low |
| claude-sonnet-5-5 run 6 (seed 604284533) | - | 0.00 | truth 35.62; no answer given |
| claude-sonnet-5-5 run 7 (seed 633675701) | 34 | 1.00 | truth 34.704; 2.0% low |
| claude-sonnet-5-5 run 8 (seed 956466926) | 28 | 0.00 | truth 36.388; 23.1% low |
| gpt-6-astra (seed 911623366) | 37.3 | 1.00 | truth 37.19; 0.3% high |
| qwen3-vl:4b-instruct-q4_K_M (seed 792092586) | - | 0.00 | truth 35.433; no answer given |
svc-bench-1
Four short drawn videos on a still camera.
No runs on this suite yet.
Method
The tasks are synthetic videos drawn by the tool, so the truth is exact: no human labels, no judge model.
The agent sees only the videos and writes its answers; bench score compares them with the truth.
The exact prompt
What bench run sends, word for word (for svc-bench-3; other suites change only the suite name and video count). One text per track, the same for every model.
Code track
You are a contender in a sports film review benchmark (suite svc-bench-3). The current folder holds 4 short videos, TASKS.md and answers.json. Read TASKS.md and follow its rules exactly: watch the videos (frames, ffmpeg, OpenCV or any script you write on the video files in this folder), then replace each null in answers.json with your answer in the stated format. Do not read the sports-video-coach package source, its git history, or any truth or result file anywhere on this machine. Work only inside this folder (temporary files under this folder are fine). Work alone, do not ask questions, and finish when answers.json is filled and parses as JSON. End with one line per task: your answer and how you got it.Frames track (Claude Code)
You are a contender in a sports film review benchmark (suite svc-bench-3, frames track). This track measures how well you review film by eye: you get still images of 4 short videos and no way to run code. Judge by looking only. Do not try to read anything outside the given images and task text, and do not start helpers or sub-agents. Work alone, do not ask questions. End your reply with the whole answers.json (keys suite, track, answers; replace each null with your answer in the stated format) in one ```json block, after one line per task: your answer and how you got it. The current folder holds TASKS.md, answers.json and the images (contact sheets in sheets/, full-size stills in frames/). Your only tool is Read: read TASKS.md first, then the images it lists.The Claude Code frames rows were run with this frames prompt. The other rows do not store their prompt in the result file, so for them it is unclear.
count
How many reps, bounces or shots.
1 - |error| / truth, never below 0.
rate
A cadence or a percentage.
1 within 2 % of the truth, falling linearly to 0 at 20 %.
timestamps
When each event happens.
Per event: 1 within 0.5 s, linear to 0 at 2 s, 0 if missing; summed and divided by the longer of the truth and answer lists, so extra events cost too.
outcomes
Made or missed, in order.
Fraction of positions answered correctly.
Total = the mean of the task scores. Above chance: per task, (score - floor) / (1 - floor), clipped to 0..1, where the floor is the score of the blind baseline (it copies the example answers from the task text and sees no video); 0 = no better than that guess, 1 = perfect. Full rules: docs/benchmark.md.
Run it yourself
- Install (needs ffmpeg on PATH)
uv tool install git+https://github.com/mariusDing/sports-video-coach@74b517fc410944fefeac2979810656ed77fb8f1a - Make the tasks: videos and an empty answers.json (the newest suite; leave out --suite for svc-bench-1)
sports-video-coach bench prepare --out bench-run --suite svc-bench-3 - Let your agent watch the videos and fill bench-run/answers.json, then score it
sports-video-coach bench score bench-run --agent "Your agent" --model "your-model" - Or do it all in one command (prepare, run headless, score): Claude Code or Codex
or a preset for another agent CLI. The presets are built from each CLI's docs (read 2026-10-25), with every flag checked against the real CLI's --help on 2026-10-25, but not run by the maintainer on a task (except OpenCode: run once, OpenCode 1.19.4, opencode/deepseek-v4.1-flash-free, 2026-10-25); code track only (doc links per flag). Any other CLI:sports-video-coach bench run --agent claude --suite svc-bench-3 sports-video-coach bench run --agent codex --suite svc-bench-3--agent cmd --cmd "... {prompt}".--agent geminiGemini CLI:gemini --approval-mode yolo [--model M] -p <prompt>(flags checked against 0.65.0 --help)--agent qwenQwen Code:qwen --safe-mode --approval-mode yolo [--model M] <prompt>(flags checked against 0.26.1 --help)--agent aiderAider:aider --yes-always --no-git --no-check-update --no-pretty --no-stream [--model M] --read TASKS.md --message-file <prompt file> answers.json(flags checked against 0.86.2 --help)--agent opencodeOpenCode:opencode run --auto --print-logs --log-level ERROR --dir <run folder> [--model M] <prompt>(flags checked against 1.19.4 --help)--agent cursorCursor CLI:agent -p --force --trust --output-format text [--model M] <prompt>(flags checked against 2026.10.22-27dcf5f --help)--agent copilotGitHub Copilot CLI:copilot -p <prompt> --allow-all-tools --no-ask-user -s [--model M](flags checked against 1.0.103 --help)--agent gooseGoose:goose run --no-session [--model M] -t <prompt>(flags checked against 1.56.0 --help)
Submit your run
- Open a pull request that adds your result file to
benchmark/results/. CI re-scores it withbench validate. Your first PR's checks start after a maintainer approves them. - No pull request? Paste the file into the benchmark result issue form.
- Rules: do not read the truth files or the package source; one run = one file; report wall time honestly.
Honesty notes
- The benchmark and this page were built with a coding agent (Claude Code).
- Every row can be rerun: same suite, same command, scores recomputed from the stored answers. A rerun's answers can differ (see the sample size note at the top).
- The author wrote the tool, drew the suites and submitted the first runs; outside runs are welcome (above).
- Failed and killed runs stay on the board and count in their contender's mean.
- Synthetic drills test counting and timing, not every part of a coach's review.